
You’ve probably run into the term in a CMS training, an SEO audit, or a meeting where someone said, “We need to clean up our metadata,” and everyone just nodded. It’s one of those words that gets used constantly and defined rarely. You’ll even see it written as one word or two, with “meta data” showing up almost as often as “metadata.”
In light of this confusion, here’s the short explanation: Metadata is data about data. Split the word in two and it gets even clearer. “Meta” means about or beyond, and “data” is the raw content itself. In plain English, metadata is the information that describes, organizes, and gives context to a piece of content, without actually being that content.
Consider a digital photo. The photo itself is the data. But when you take that photo, you also create metadata like the date it was taken, the location where it was shot, and the camera model that took it. None of that information is visible in the image itself. But it’s there in that invisible data layer that allows you to search your photo library by place or date instead of scrolling through years of images one at a time.
Those same principles are applicable to just about everything else you touch online. A blog post has a publish date and an author byline. A product listing has a category and an SKU. A customer record in a CRM has a created-on date and an owner. All of this is metadata, and it’s the connective tissue that makes content and data usable at scale.
Metadata vs. Data: What’s the Difference?
This is the question that trips up almost everyone the first time they run into this topic. Think of a library. The book on the shelf is the data. The card catalog entry (the book’s title, author, subject, and shelf location) is the metadata that tells you the book exists and where to find it.
- Data is the actual content, file, or record itself. The book, the photo, the webpage, the row in a database.
- Metadata is the structured information describing that content. What it is, who made it, when, and how it connects to everything else around it.
Without metadata, data just piles up. A folder of ten thousand unlabeled files is technically full of information, but good luck finding anything in it. Metadata is what turns that pile into something you can search, sort, and trust, no matter what kind of content it holds. Some people call this “meta information” instead of metadata, but the value is the same either way. It’s what makes raw data usable.
Types of Metadata
Most metadata falls into one of three buckets, and each one has different characteristics and elements, from a webpage’s tags to metadata for files sitting in a shared drive.
Descriptive Metadata
Descriptive metadata answers the question, “What is this?” It includes information like the title, author, publish date, and tags on a blog post, or the name and category on a product page. These are common examples of metadata many users interact with without noticing because it’s the information people use to find and identify something in the first place.
Structural Metadata
Structural metadata answers the question, “How is this organized?” It defines the relationships between pieces of content and helps systems understand how information fits together. For example, it can indicate that a group of pages belongs to the same chapter, that a document should be read in a specific order, or that a webpage is divided into sections and subsections. While users may not see it directly, structural metadata helps keep content organized and navigable.
Administrative Metadata
Administrative metadata answers the question, “How is this managed?” This includes file type, permissions, ownership, and usage rights. Metadata standards and a shared metadata schema, like Dublin Core, exist so different teams and tools can read the same fields the same way, instead of everyone building their own system from scratch.
Why Is Metadata Important?
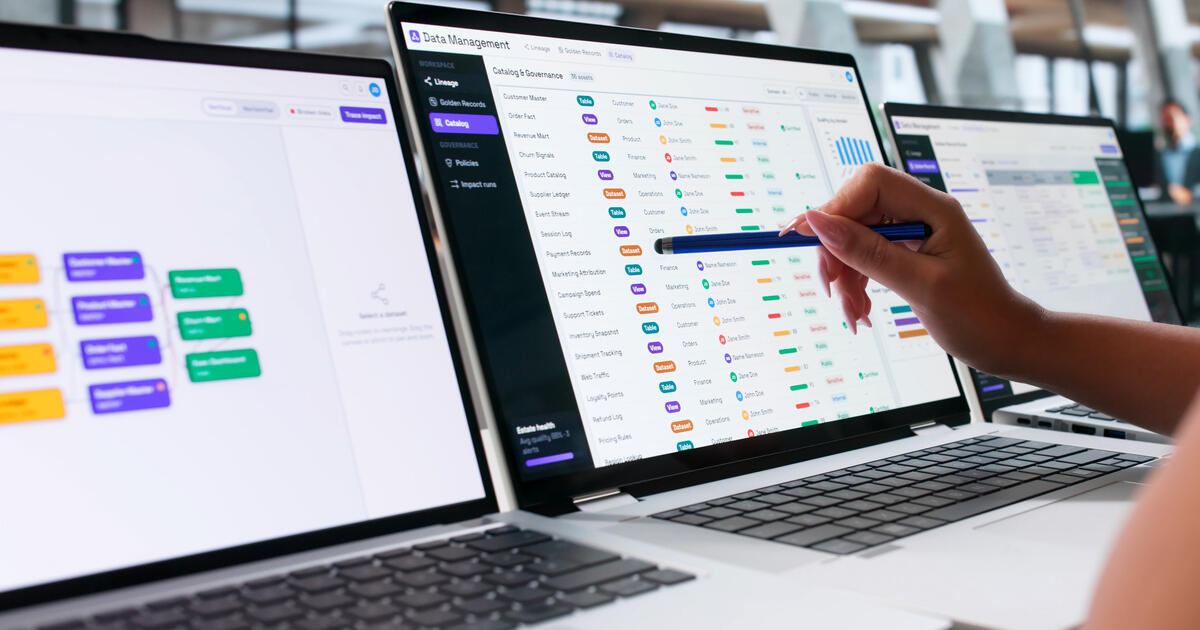
So why is metadata important? The benefits of metadata mostly come down to one thing: it helps you find specific data fast instead of digging for it. Here’s what metadata is used for in practice, broken into the four places where the value is most apparent:
| Function | Value for Brands |
|---|---|
Discovery & Findability | If your metadata is a mess, so is your search. This is what lets people and search engines find the right thing quickly. |
Governance & Trust | Who made this, when, and can you trust it? Metadata is what answers those questions once a content library grows so large that one person can’t remember it all. |
Quality & Consistency | Standardized metadata keeps duplicate and near-duplicate content from piling up as a library grows. It also makes the content you do have easier to audit. |
AI Readiness | AI systems are only as good as the metadata they’re working from. So, if you feed an AI solution messy, inconsistent data, it’s likely it will confidently serve up outdated or duplicate content right alongside the accurate stuff. |
That last point is worth sitting with, because it’s becoming the crux of a much bigger conversation. As AI solutions mature and use cases expand, organizing your metadata and investing in content operations, such as with a Digital Asset Management (DAM) system, can provide significant benefits.
Metadata in SEO & Content Marketing
For marketers and SEO practitioners, metadata is more than a behind-the-scenes technical detail. It influences how content appears in search results, how search engines interpret a page, and how easily users can find the information they're looking for.
| Metadata Type | Value for SEO & Content Marketing |
|---|---|
Title Tags & Meta Descriptions | The title tag is often the first metadata element marketers optimize because it directly influences how a page appears in search results. A clear, relevant title helps search engines understand the page's topic, while the meta description serves as ad copy that can encourage clicks. Even when search engines rewrite them, well-crafted titles and descriptions provide important context about the page and improve the likelihood that the right users find and engage with your content. |
Schema & Structured Data | Schema markup adds standardized metadata that helps search engines understand entities, relationships, and a page’s purpose beyond what can be inferred from the visible content alone. Product, FAQ, Article, Organization, and other schema types help search platforms understand entities and relationships more accurately, which can improve how content is displayed in search results and AI-generated experiences. |
Sitemaps | A sitemap provides search engines with metadata about your site's URLs, content hierarchy, and update history. While it doesn't guarantee indexing, it helps crawlers discover new pages, understand site structure, and prioritize recently updated content. As websites grow larger and more complex, maintaining an accurate sitemap helps ensure valuable content remains visible and accessible to search engines. |
The importance of metadata continues to grow as search evolves. Seer Interactive found that pages cited in a Google AI Overview earn approximately 120% more organic clicks per impression than pages that are not cited for the same query. While multiple factors influence those citations, accurate metadata and structured data help provide the context search engines and AI systems use to interpret and surface content.
If you have questions about how your site is showing up in search experiences, consider a professional SEO analysis to identify and resolve the hidden issues limiting your brand’s visibility.
Metadata Management Best Practices
Knowing what metadata is and managing it successfully are two different things. As content libraries grow, small inconsistencies in naming, tagging, categorization, and ownership can make content harder to find, organize, and trust. Effective metadata management helps prevent those issues before they become serious problems.
| Metadata Best Practice | Value for Brands |
|---|---|
Establish a consistent framework early. | Decide on fields and standards before content volume forces your hand, not after. Establishing a basic metadata framework in the beginning saves a much messier cleanup later on. |
Choose the right structure for the job. | Flat tags work fine for simple categorization. But content with real parent-child relationships, like a product catalog with categories and subcategories, needs an actual taxonomy. |
Treat it as ongoing governance, not a one-time setup. | Metadata needs regular auditing as libraries grow, or you end up with what people call metadata debt, a pile of outdated, inconsistent fields quietly working against your search, reporting, and AI performance. |
For enterprise organizations, metadata management practices may need to be formalized a bit further. A dedicated metadata management tool, a metadata program with defined mapping and modeling rules, or organization-wide standards for content ownership, taxonomy, and classification all become worthwhile investments once a content library gets big enough to outgrow ad hoc tagging.
Why Work with Americaneagle.com for Your SEO & Content Strategy?
Metadata is important because it influences how search engines understand your content, how AI-powered experiences discover and cite your pages, and how efficiently internal teams can manage growing content libraries. Getting it right requires a thoughtful approach to content architecture, taxonomy, structured data, and search optimization.
Americaneagle.com helps organizations solve these challenges every day. Our SEO and digital marketing teams work with mid-market and enterprise brands across industries, helping them audit content, improve metadata standards, implement structured data, and build content ecosystems that are easier to manage and easier to find through search.
Whether you're modernizing a CMS, evaluating a DAM platform, cleaning up years of inconsistent metadata, or looking to improve visibility in traditional and AI-powered search, Americaneagle.com can help you create a scalable strategy that supports both today's search landscape and tomorrow's opportunities. Explore our SEO services or contact our team to learn how we can help.
Related FAQs
What is metadata in simple terms?
Metadata is data about data. It’s the information that describes something, like a photo’s date and location or a webpage’s title and description, without being the thing itself.
What is the difference between data and metadata?
Data is the actual content or file, such as a photo, webpage, or database record. Metadata is the structured information describing that content, including what it is, who created it, and when.
What are the main types of metadata?
There are three main types. Descriptive metadata covers what content is about, structural metadata covers how pieces of content relate to each other, and administrative metadata covers how content is managed, including permissions and rights.
Why is metadata important for SEO?
Metadata elements like title tags, meta descriptions, and schema markup shape how a page shows up in search results and how eligible it is for rich results and AI Overview citations, both of which affect click-through rate.
What is metadata management?
It’s the ongoing practice of setting consistent metadata standards, structuring metadata appropriately for the content type, and auditing it regularly as a library or platform grows.
Is metadata the same thing as a meta tag?
Not quite. A meta tag is one specific type of metadata, usually HTML code like a title tag or meta description living in a webpage’s head section. Metadata is the broader category that meta tags fall under.
What is structured data, and how does it relate to metadata?
Structured data, usually implemented as schema markup, is metadata formatted in a standardized way so search engines and AI systems can read and categorize it consistently. It’s one of the more technical applications of metadata in SEO.